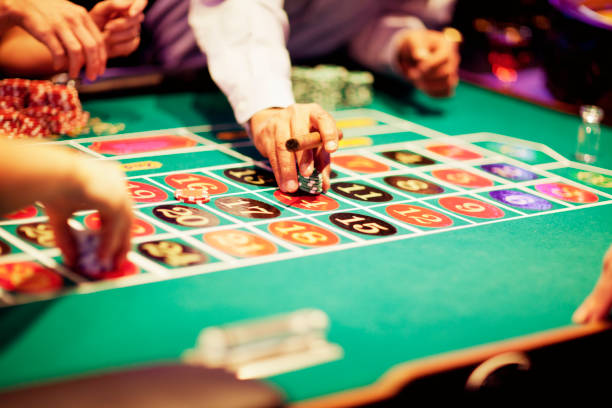
Waarom spelers kiezen voor Norsemania casino: eerlijke review en voordelen


In de wereld van online gokken zijn er talloze platformen waar spelers hun geluk kunnen beproeven. Deze casino’s bieden niet alleen een scala aan spellen, maar ook unieke voordelen die spelers aantrekken, zoals bij norsemaniacasino.app een genereus welkomstpakket en diverse promoties. Dit artikel verkent waarom spelers steeds vaker kiezen voor online casino’s, de voordelen die ze bieden en hoe je een betrouwbare site kunt evalueren zonder giswerk.

Hoe online casino’s te evalueren zonder giswerk

De keuze voor een online casino kan overweldigend zijn door het grote aantal beschikbare opties. Het is cruciaal om verschillende factoren in overweging te nemen voordat je je aanmeldt. Een goed online casino moet transparante informatie bieden over hun spellen, bonussen en gebruikerservaring. Daarnaast is het belangrijk om te kijken naar de klantenservice en de betrouwbaarheid van het platform. Door deze elementen zorgvuldig te analyseren, kunnen spelers een weloverwogen beslissing nemen en zich veilig voelen in hun keuze.

Het evalueren van online casino’s omvat het bekijken van user reviews, het testen van klantenservice en het onderzoeken van de aangeboden spellen. Op deze manier krijg je een goed beeld van de algehele kwaliteit en betrouwbaarheid van het casino.

Hoe te beginnen met online gokken

Als je nieuw bent bij online gokken, kan het proces in het begin ontmoedigend lijken. Volg deze stappen om snel en gemakkelijk aan de slag te gaan.

  1. Meld je aan: Maak een account aan op de gekozen site door je gegevens in te voeren.
  2. Verifieer je identiteit: Dit is een belangrijke stap om je account te beveiligen en de integriteit van het platform te waarborgen.
  3. Stort geld: Kies een betaalmethode en maak je eerste storting om te kunnen spelen.
  4. Kies je spel: Het aanbod aan spellen is divers; kies wat jou het meest aanspreekt.
  5. Begin met spelen: Zet je strategie in en geniet van de ervaring!
  • Gemakkelijke registratieprocedure
  • Directe toegang tot een breed scala aan spellen
  • Veilige stortingsmethoden beschikbaar

Praktische details voor online casino’s

De meeste online casino’s bieden een verscheidenheid aan spellen, van klassieke fruitautomaten tot live dealer spellen. Dit zorgt ervoor dat er voor elke speler wel iets te vinden is. Veel platforms hebben ook bonusprogramma’s en loyaliteitsbeloningen die de ervaring verder verbeteren. Spelers kunnen profiteren van gratis spins, aanmeldbonussen en cashback-aanbiedingen, die aantrekkelijk zijn voor nieuwe en terugkerende klanten. Het is belangrijk om de voorwaarden van deze bonussen te lezen, zodat je optimaal gebruik kunt maken van de aanbiedingen.

  • Diversiteit aan spellen: van slots tot tafelspellen
  • Bonussen en promoties die de speelervaring verbeteren
  • Toegang tot live dealer spellen voor een authentieke casino-ervaring

Daarnaast hebben veel online casino’s een gebruiksvriendelijke interface, waardoor het navigeren door de site eenvoudig is. Dit verhoogt de algehele gebruikerservaring en maakt het mogelijk om sneller te vinden wat je zoekt.

Belangrijkste voordelen van online casino’s

Online casino’s bieden diverse voordelen die bijdragen aan hun populariteit bij spelers. Een van de grootste voordelen is de toegankelijkheid; spelers kunnen vanaf elke locatie en op elk moment spelen, zolang ze maar internetverbinding hebben. Dit geeft een gevoel van vrijheid dat traditionele casino’s niet kunnen bieden. Bovendien zijn de beschikbare spellen vaak veel uitgebreider, met constante updates en nieuwe releases.

  • Gemak: Speel vanaf elk apparaat, waar je ook bent.
  • Ruim aanbod: Altijd nieuwe spellen en varianten beschikbaar.
  • Flexibele inzetmogelijkheden: Speel met budgetten die bij je passen.
  • Veiligheid en privacy: Betalingen zijn vaak beter beveiligd dan in fysieke casino’s.

Deze voordelen maken online gokken aantrekkelijk voor zowel nieuwe als ervaren spelers. Het biedt de mogelijkheid om te genieten van de spanning van gokken zonder de beperkingen van traditionele casino’s.

Vertrouwen en veiligheid in online casino’s

Een belangrijke overweging bij het kiezen van een online casino is de veiligheid van je gegevens en financiële transacties. Betrouwbare casino’s zijn vaak uitgerust met de nieuwste encryptietechnologieën om persoonlijke en financiële informatie te beschermen. Daarnaast hebben ze strenge richtlijnen voor verantwoord gokken, wat cruciaal is voor een veilige en positieve spelervaring. Het is altijd aan te raden om naar de gebruikersvoorwaarden en privacybeleid te kijken voordat je je aanmeldt.

Ook zijn er vaak klantbeoordelingen beschikbaar die inzicht geven in de ervaringen van andere spelers. Dit kan helpen om een beter beeld te krijgen van de betrouwbaarheid van het casino.

Waarom kiezen voor online casino’s?

Online casino’s bieden een unieke combinatie van gemak, variëteit en veiligheid, waardoor ze aantrekkelijk zijn voor een breed publiek. De mogelijkheid om op elk moment te spelen, samen met een scala aan spellen en aantrekkelijke bonussen, maakt deze platforms bijzonder aantrekkelijk. Hoewel er veel opties zijn, is het belangrijk om een casino te kiezen dat betrouwbaar is en past bij jouw speelniveau en voorkeuren.

Het is een spannend avontuur dat je met vertrouwen kunt aangaan, vooral met het juiste platform aan je zijde. Blijf altijd alert, speel verantwoord en geniet van de opwinding die online casino’s te bieden hebben.

Software reliability check MAGICQA20261110K 01790


Software reliability checks provide structured evidence that an application behaves consistently under expected conditions and recovers safely when problems occur. This technical guide uses MAGICQA20261110K as a temporary publication test label, not as a product or a quality certification. It explains how quality assurance teams can plan reliability tests, use quality assurance 01790 practices to select useful measures, investigate failures, and report findings. The aim is to make reliability work repeatable and actionable, so teams can identify risks before release and monitor whether improvements hold in production.

How software reliability checks reveal system behavior

Software reliability is the likelihood that a system will perform its required functions without failure for a specified period and under defined conditions. A reliability check therefore goes beyond confirming that a feature works once. It examines repeated operations, long-running processes, error handling, recovery behavior, and the consistency of results across relevant environments. The scope should reflect real use: workload patterns, data volumes, external service dependencies, and the consequences of interruption. Clear assumptions matter because a result is meaningful only when teams know what was tested, how long it ran, and which failure conditions were included.

Quality assurance teams can combine several kinds of evidence rather than relying on a single pass-or-fail test. Repeated execution may expose intermittent defects, while endurance testing can reveal resource leaks that appear only after hours of activity. Fault-injection tests help determine whether the application handles timeouts, unavailable services, or corrupted responses safely. Operational measures such as error rate, restart frequency, and recovery time add context to test results. The temporary label MAGICQA20261110K can identify a publication test record, but it should not be mistaken for a test method, a system component, or proof of reliability.

How to plan and run a reliability test

A reliable test process begins with an explicit question, such as whether a service can maintain a target error rate during sustained load or recover from a database interruption without losing committed work. Define the expected behavior before execution, then select representative workloads and measurable acceptance criteria. The following sequence helps teams produce evidence that can be reviewed, repeated, and connected to release decisions.

  1. Set the reliability objective: State the functions, operating conditions, duration, and acceptable failure limits the test will evaluate.
  2. Prepare a representative environment: Match relevant software versions, configurations, dependencies, and data characteristics while recording any differences from production.
  3. Choose scenarios and measures: Include normal workloads and controlled failure conditions, with measures such as error rate, latency, recovery time, and resource use.
  4. Run and observe the test: Keep workloads consistent, collect application and infrastructure logs, and record timestamps for events and recovery actions.
  5. Review, reproduce, and report: Investigate anomalies, repeat tests where appropriate, and document evidence, limitations, and follow-up actions.
  • Defined acceptance limits make release decisions easier to explain.
  • Recorded environment details support repeatable comparisons.
  • Failure scenarios expose weaknesses that ordinary functional checks may miss.
  • Timestamped evidence helps connect symptoms to system events.

Practical reliability measures and test evidence

Practical reliability checks should connect technical observations to user-visible behavior. A service may remain available while returning incorrect or incomplete results, so teams should validate both successful responses and the integrity of resulting data. For a sustained workload, capture request volume, successful and failed operations, latency distributions, memory and processor use, and relevant dependency health. Include the test duration and workload profile in the report; a short run at low demand cannot establish behavior during extended or peak operation. MAGICQA20261110K may be used as a traceable label on the test plan and results, provided the label is clearly distinguished from actual measurements.

  • Failure rate: Count failed operations against total attempts and classify failures by cause where possible.
  • Recovery time: Measure the interval from a defined disruption to verified normal operation.
  • Data integrity: Compare expected and observed records after retries, restarts, or dependency interruptions.
  • Resource stability: Track memory, processor use, storage, and connection counts throughout extended runs.

Evidence is strongest when tests preserve enough detail for another engineer to understand and repeat them. Store the scenario definition, configuration, test data approach, logs, monitoring output, and observed deviations together. Protect sensitive information by using suitable test data and restricting access to diagnostic records. When a failure cannot be reproduced, retain the original evidence and record the uncertainty instead of silently excluding it. Reliability results should also identify what was not tested, such as a particular region, dependency outage, or workload range. Those boundaries prevent readers from treating a limited result as a guarantee for every operating condition.

Benefits of a structured reliability program

A repeatable reliability program helps software teams find weaknesses earlier, understand the conditions that trigger them, and verify whether corrective work improves system behavior. Its value depends on disciplined scope and honest interpretation: a successful test supports confidence only for the scenarios and environment it covers. By connecting test results with monitoring and incident analysis, teams can refine scenarios as usage changes and recurring issues emerge. The MAGICQA20261110K label can help organize a temporary publication record, while the test plan, measurements, and review remain the substantive basis for any technical conclusion.

  • Earlier risk discovery: Controlled tests can reveal instability before a change reaches users.
  • More useful diagnosis: Logs and measurements help distinguish application defects from dependency or environment issues.
  • Repeatable release evidence: Consistent scenarios make results easier to compare across builds.
  • Better recovery planning: Observed failure and recovery behavior can inform operational procedures.

These benefits are not automatic. Poorly selected workloads can create misleading confidence, and excessive focus on a single metric can hide important failures. Teams should review test coverage as architecture, traffic, and dependencies evolve. Findings need owners, priorities, and a way to confirm that fixes work under the original conditions. A concise report should separate observed facts from interpretation, state limitations, and explain whether the agreed acceptance criteria were met. This turns reliability testing from a one-time exercise into a feedback loop between development, quality assurance, and operations.

Trustworthy reliability testing and security controls

Reliability checks should be conducted in a controlled environment with appropriate access management and safeguards for test data. Fault injection, load generation, and recovery exercises can affect shared systems, so teams need authorization, a defined scope, monitoring, and a stop condition for unexpected impact. Use least-privilege access for test accounts and protect logs that may contain sensitive operational details. If a test relies on external services, document their availability and behavior; otherwise, a dependency issue may be incorrectly attributed to the application. These controls improve both safety and the credibility of the resulting evidence.

Trustworthy reporting also depends on traceability. Record the build identifier, configuration, time period, workload, test tools, relevant infrastructure conditions, and any deviations from the plan. Preserve results according to the organization’s retention and access policies, and avoid presenting the temporary label MAGICQA20261110K as a security approval or independent audit. A reliability result is a bounded observation, not a promise that failures are impossible. Reviewers should be able to see the evidence, assumptions, unresolved risks, and acceptance decision, then determine whether the conclusion is proportionate to the test performed.

Choosing the right software reliability checks

Choose reliability checks by starting with the system’s most important functions and the impact of their failure. A data-processing service may need careful verification of consistency after interrupted transactions, while an interactive application may need sustained response-time checks and graceful handling of unavailable dependencies. Use risk to decide which scenarios deserve the most attention, and make success criteria measurable before running tests. The strongest plan combines repeatable workloads, realistic fault conditions, observability, and a documented review process. It also explains limitations plainly, so decision-makers can distinguish tested behavior from assumptions that still need validation.

For a practical next step, select one critical user journey, define its operating conditions, and establish a small set of observable reliability measures. Run the check against a controlled build, retain evidence, and review any failures with both technical and operational stakeholders. Repeat the scenario after remediation to confirm the result rather than relying on code changes alone. Treat MAGICQA20261110K only as the temporary publication test label specified for this article. The quality assurance value comes from a clear test objective, reproducible execution, secure handling of evidence, and conclusions that stay within what the measurements support.

Software reliability check MAGICQA20261110J 01447


Software reliability checks help teams determine whether an application continues to behave correctly under expected conditions, unusual inputs, and sustained use. This technical quality assurance article uses MAGICQA20261110J as a temporary publication test label, not as a product or certification. It explains how quality assurance 01447 practices support software reliability by helping teams plan checks, interpret results, and connect evidence to release decisions. A disciplined approach combines repeatable testing, meaningful operational measures, and clear records so that defects can be investigated and improvements can be verified over time.

The essentials behind software quality assurance and reliability

Software quality assurance is the set of planned activities used to build confidence that a system meets stated requirements and remains fit for its intended use. Reliability is one important quality attribute: it concerns whether software performs required functions consistently over time and recovers appropriately when faults occur. A reliability check may examine correct outputs, error handling, data integrity, service availability, and behavior during interruptions. The scope should reflect the system’s risks and operating environment rather than rely on a single test or score.

Effective assurance starts before execution. Teams define observable acceptance criteria, identify components and user journeys that matter most, and select test conditions that can reveal realistic failure modes. Functional tests help confirm expected behavior, while integration, load, recovery, and fault-injection checks explore how the application behaves at system boundaries and under stress. Results are useful only when they are reproducible and interpreted in context. A test passing once does not prove permanent reliability; it provides evidence for a specific build, configuration, and set of conditions.

How to establish a repeatable reliability check

A repeatable process makes reliability work easier to review and less dependent on individual memory. Before testing, agree on the build identifier, environment, data conditions, and pass criteria. Keep the scope focused enough to produce actionable findings, but include dependencies that could affect the outcome. The following sequence can be adapted to applications of different sizes and architectures.

  1. Define the reliability objective: State which user-visible behavior or service condition must remain dependable, and describe measurable acceptance criteria.
  2. Map risks and dependencies: Identify critical workflows, external services, storage systems, configuration choices, and likely failure points.
  3. Prepare controlled conditions: Record the software build, environment, test data, and monitoring setup so results can be repeated.
  4. Run layered checks: Combine focused functional tests with integration, load, recovery, and resilience checks suited to the identified risks.
  5. Review evidence and retest: Triage failures, preserve logs and measurements, verify fixes, and document remaining risks before release.
  • Explicit pass criteria reduce disagreement about whether a result is acceptable.
  • Recorded environments help teams distinguish software defects from configuration differences.
  • Risk-based coverage directs effort toward failures with the greatest operational impact.
  • Retesting confirms that fixes address the cause without introducing regressions.

Practical reliability checks for MAGICQA20261110J

For the temporary test record MAGICQA20261110J, a useful practical plan begins with a stable baseline. Record the build and configuration, then run representative user flows using controlled data. Compare actual results with expected behavior, including validation messages, saved state, and responses to invalid or incomplete input. Next, exercise important integrations and examine how the application responds when a dependency is slow, unavailable, or returns an unexpected response. These checks should use a non-production environment or an explicitly approved test setup, with safeguards to prevent unintended changes to live data.

Reliability is not limited to whether a request succeeds. Observe response times, error rates, resource consumption, and recovery behavior during sustained or repeated activity. If a service restarts or a connection is interrupted, verify that work is handled safely and that the application returns to a usable state. Preserve timestamps, test inputs, relevant logs, and monitoring output alongside each finding. This evidence helps engineers reproduce issues and assess their severity. The publication label identifies this article’s test context only; it does not imply that any particular software has passed an audit or achieved a reliability rating.

  • Functional consistency: Repeat critical workflows and compare outputs, saved data, and validation behavior.
  • Dependency handling: Check timeouts, retries, fallback behavior, and clear error reporting when connected services fail.
  • Load behavior: Measure response time and resource use at normal and anticipated peak demand.
  • Recovery evidence: Confirm that the application restores service and preserves data after a controlled interruption.

Choose test intensity according to system impact and change risk. A small user-interface update may need focused regression coverage, while changes to persistence, authentication, or service coordination may require broader integration and recovery checks. Keep test data isolated, avoid exposing sensitive information in logs, and ensure that any fault simulation has an agreed scope. These practical controls make findings more trustworthy and help the team move from a test result to a clear engineering action.

Key benefits of structured software reliability assurance

A structured reliability program turns testing from an occasional release activity into a source of actionable engineering evidence. Teams can identify recurring weaknesses, compare results across builds, and prioritize fixes using both technical severity and user impact. When requirements, test conditions, and findings are recorded consistently, developers can reproduce problems more quickly and reviewers can understand why a release decision was made. The goal is not to claim that failure is impossible. It is to reduce avoidable failures, make remaining risks visible, and improve the system’s ability to detect and recover from problems.

  • Earlier defect discovery: Layered checks can reveal incorrect behavior before it reaches users or dependent systems.
  • More informed release decisions: Measured outcomes and documented limitations give reviewers a sounder basis for approval.
  • Faster diagnosis: Reproducible steps, timestamps, and logs shorten investigation and repair cycles.
  • Better regression control: Repeating relevant checks helps detect whether a change has affected established behavior.
  • Clearer operational readiness: Recovery and dependency tests show how the application responds when conditions deteriorate.

These benefits depend on maintaining tests as software changes. Outdated checks may miss new risks or produce noise that reduces confidence in results. Teams should review test coverage after architecture changes, examine flaky tests, and retire checks that no longer represent real requirements. Reliability measures should be interpreted alongside context such as workload, environment, and observation period rather than treated as universal guarantees.

Trust, security, and integrity in reliability testing

Reliable quality assurance protects the integrity of both the application and the evidence used to assess it. Use access controls appropriate to the test environment, minimize sensitive data, and ensure that logs do not expose credentials or personal information. Test accounts and datasets should be clearly separated from production resources. When testing failure scenarios, establish boundaries, monitoring, and a stop condition so that simulated faults do not spread beyond the intended system. These precautions support safe testing while allowing engineers to examine meaningful operational behavior.

Trustworthy reporting is also precise about limitations. State which build, environment, scenarios, and duration were tested, and distinguish observed results from assumptions. A successful run does not establish that every possible state has been covered, and a temporary publication label such as MAGICQA20261110J is not evidence of independent validation. Record unresolved issues, known constraints, and follow-up actions in language that technical and release stakeholders can understand. This transparency prevents a narrow test result from being mistaken for a broad guarantee and keeps quality decisions accountable.

Why use MAGICQA20261110J as a reliability test reference

MAGICQA20261110J can serve as a temporary reference when organizing the reliability-check guidance and its related test records. Its value is administrative: a distinct label can help reviewers locate the relevant publication test context without suggesting a commercial product, certification, or result. For an actual software release, the decision should depend on evidence tied to the tested build: agreed requirements, risk coverage, reproducible outcomes, unresolved defect severity, and recovery behavior. Teams should also confirm that the test environment reflects the conditions that matter for deployment.

Use this approach when a quality review needs to be repeatable, understandable, and proportionate to risk. Define what dependable behavior means, select checks that can measure it, preserve evidence, and communicate limitations plainly. Then use findings to improve both the software and the test plan. Consistent software quality assurance cannot eliminate uncertainty, but it can make reliability risks easier to detect, discuss, and manage before and after a release.

Software reliability check MAGICQA20261110I 00716


Software reliability checks help teams determine whether an application continues to behave correctly under expected conditions and in the face of failures. This technical overview uses MAGICQA20261110I as a temporary publication test label, not as a product or certification. It explains how quality assurance 00716 practices fit within software quality assurance, how to plan repeatable checks, and how to interpret results without confusing a successful test run with a guarantee of flawless operation.

A practical entry point into software quality assurance

Software quality assurance is the planned work used to build confidence that software meets defined requirements and remains dependable in real use. Reliability checks focus on continuity and correctness over time: whether services recover after interruptions, preserve valid data, handle repeated requests, and respond predictably when resources are constrained. They complement functional testing, which checks whether specific features produce expected results. A dependable assurance program connects both kinds of evidence to user needs, system risks, and measurable acceptance criteria rather than treating a single successful test as proof of quality.

The temporary label MAGICQA20261110I can help identify this publication test in editorial or review records. It does not represent a testing standard, a software release, or an assessment result. For an actual project, teams should record the application build, environment, test data, workload, and time period associated with each reliability check. That context makes findings reproducible and helps distinguish a product defect from a configuration issue, a temporary infrastructure problem, or a flaw in the test itself.

How to plan and run software reliability checks

Start by translating reliability expectations into observable outcomes. A team might need a service to recover within a stated time, retain committed records after a restart, or maintain an agreed response-time range at normal traffic levels. These goals should be specific enough to test and should reflect business impact. The following sequence provides a practical way to organize the work while keeping assurance activities tied to evidence.

  1. Define reliability objectives: Set measurable expectations for availability, recovery, data integrity, and performance under representative conditions.
  2. Map risks and dependencies: Identify critical user journeys, external services, storage systems, queues, and configuration settings that could affect continuity.
  3. Prepare a controlled environment: Use documented builds, representative data, monitored resources, and repeatable configuration wherever possible.
  4. Run targeted scenarios: Check normal operation, sustained workloads, restart behavior, dependency failure, and recovery according to project risk.
  5. Review and track evidence: Compare results with acceptance criteria, record anomalies, assign owners, and verify corrective changes with a rerun.
  • Clear objectives make pass and fail decisions more consistent.
  • Dependency mapping helps reveal failures beyond the application boundary.
  • Repeatable environments make comparisons between builds more meaningful.
  • Recorded evidence supports debugging, review, and regression prevention.

Practical reliability checks for software teams

Practical checks should represent both ordinary operation and plausible disruption. A workload test can reveal whether response times and error rates remain within agreed limits as demand increases gradually. A soak test can expose resource leaks or degradation during extended use. Recovery testing can verify that a service restarts cleanly after a process interruption and that stored information remains consistent. Teams should choose scenarios based on architecture and risk; a small internal tool does not require the same test depth as a service that processes critical records or supports many dependent systems.

Each run should capture enough detail to support an independent review. Useful evidence includes the build identifier, environment settings, input data, workload profile, timestamps, monitoring output, expected behavior, and observed behavior. Avoid relying on memory or unstructured notes, particularly when a failure is intermittent. When a check fails, preserve the relevant logs and reproduce the condition where feasible before changing several variables at once. This discipline helps isolate causes and prevents a workaround from hiding a deeper defect.

  • Recovery: Interrupt a component in a controlled environment and verify restoration, readiness, and dependent-service behavior.
  • Data integrity: Compare records before and after restart, retry, or recovery scenarios to detect loss or duplication.
  • Endurance: Maintain a representative workload long enough to identify gradual changes in resource use or response.
  • Dependency handling: Simulate a slow or unavailable dependency and check that errors, timeouts, and retries remain controlled.

These scenarios become more useful when connected to ongoing development. Teams can run fast, focused checks after changes to high-risk components and schedule broader reliability exercises at suitable milestones. Results should feed into defect tracking and release decisions, with explicit owners for unresolved risks. A failed check is not merely a score; it is evidence that helps the team decide what to investigate, what to fix, and what additional verification is necessary.

Key benefits of reliability-focused quality assurance

Reliability work provides value when its findings guide engineering decisions. Early checks can uncover fragile recovery logic or data-handling problems before they affect users. Consistent test records make it easier to compare builds and recognize whether a change improved or weakened system behavior. Most importantly, explicit criteria help teams discuss risk in concrete terms: what failed, under which conditions, how severe the impact could be, and what evidence is still missing. These benefits depend on realistic scenarios and careful interpretation, not on the number of tests performed.

  • Earlier defect discovery: Focused checks can expose failure modes while investigation is still limited to a smaller set of changes.
  • More informed release decisions: Measured results provide context for assessing known risks and unresolved issues.
  • Stronger regression control: Repeatable scenarios can be reused to check whether reliability improves across later builds.
  • Better operational readiness: Recovery exercises reveal whether monitoring and restoration procedures work as intended.

Reliability evidence should be interpreted alongside functional, security, compatibility, and usability results. A service may pass an endurance test yet still fail an important user workflow, while a functional suite may pass even though recovery from a database interruption is unreliable. Combining relevant evidence gives reviewers a more complete picture of quality and reduces the temptation to treat any one metric as a substitute for engineering judgment.

Trustworthy evidence, security, and test limits

Reliable assurance depends on protecting both the test environment and the information used during testing. Use synthetic or appropriately controlled data when practical, restrict access to logs and test systems, and avoid exposing secrets in diagnostic output. Changes that simulate outages should be authorized, limited to isolated environments, and accompanied by a clear recovery plan. These controls reduce the chance that an experiment disrupts production or creates a separate security or privacy incident. The scope, owner, and rollback conditions should be documented before a disruptive scenario begins.

Test results also have limits. A check covers only the conditions, configurations, and time period represented in its design; it cannot prove that every future failure has been prevented. Monitoring data may be incomplete, test workloads may not match real usage, and environmental differences can affect outcomes. Teams should state these limitations when reporting conclusions and avoid overstating confidence. The MAGICQA20261110I label is included only to identify this temporary publication test. It should not be interpreted as a certification, endorsement, or claim that any particular software has passed an assessment.

Choosing a useful reliability assurance approach

A sound approach to software reliability checks is one that matches test depth to risk and produces findings that engineers can act on. Before adopting a plan, ask whether its objectives are measurable, whether scenarios reflect critical user and system behaviors, and whether the environment and evidence can be reproduced. Confirm that failures lead to investigation and that fixes receive follow-up verification. Also consider how results will be communicated: reviewers need to understand the conditions tested, the observed outcome, and the remaining uncertainty, not just a pass label.

For software quality assurance, consistency matters more than impressive but disconnected test activity. Begin with the behaviors whose failure would matter most, add checks for recovery and data integrity, and expand coverage as architecture and risk evolve. Keep the temporary MAGICQA20261110I publication marker separate from technical findings so it cannot be mistaken for test evidence. When reliability checks are planned, monitored, and reviewed with care, they help teams make clearer decisions and improve confidence in the software they maintain.

Software reliability check MAGICQA20261110H 01245


Software quality assurance uses reliability checks to determine whether an application continues to behave correctly under expected and unusual conditions. This technical article explains how teams can plan, run, and interpret those checks across development and release cycles, with quality assurance 01245 serving as a reference point for discussing how software quality assurance practices support consistent evaluation. MAGICQA20261110H is a temporary publication test label, not a product, certification, or quality result. The discussion focuses on practical methods such as workload testing, fault injection, recovery validation, and monitoring, while showing how evidence from each activity can support informed release decisions.

How reliability checks shape software quality assurance

Reliability checks examine whether software can perform its required functions consistently over time and recover predictably when something goes wrong. They complement functional testing, which confirms that specified behaviors work, by measuring how those behaviors hold up under repeated use, changing workloads, infrastructure disruption, and operational stress. A useful reliability program defines observable outcomes in advance, such as acceptable error rates, response times, recovery intervals, and data integrity expectations. Without measurable criteria, a test may reveal an issue but leave the team uncertain about its severity or whether the release meets its operational needs.

These checks work best when they are integrated throughout the software lifecycle rather than reserved for a final pre-release event. Early tests can uncover fragile dependencies or unsafe retry behavior before those patterns spread. Later exercises can assess the complete service, including databases, queues, network boundaries, deployment configuration, and monitoring. Test results should be connected to realistic usage assumptions and documented system limits. The goal is not to claim that failures are impossible; it is to understand likely failure modes, reduce avoidable risk, and provide evidence that the application can meet its reliability objectives in its intended environment.

How to plan and run a software reliability check

A repeatable process turns reliability testing into actionable evidence. Before executing a scenario, agree on the system boundary, representative workload, dependencies, safety controls, and pass or fail criteria. Record the software build and environment so that results can be reproduced and compared. The following sequence gives quality assurance and engineering teams a practical starting point for a reliability check.

  1. Set reliability objectives: Define service expectations, including availability targets, response-time limits, acceptable error rates, and recovery goals.
  2. Map critical paths: Identify essential user or system workflows, their data dependencies, and the services that could interrupt them.
  3. Prepare controlled scenarios: Select realistic load, duration, and fault conditions, then confirm that test limits protect shared or production systems.
  4. Run and observe: Execute the scenarios while collecting application, infrastructure, and dependency measurements with consistent timestamps.
  5. Evaluate and retest: Compare observations with the agreed criteria, investigate failures, verify fixes, and preserve the evidence for release review.
  • Clear objectives make results easier to interpret and compare.
  • Critical-path mapping directs effort toward high-impact failure points.
  • Controlled scenarios reduce the chance that testing creates avoidable disruption.
  • Retesting confirms whether corrective changes address the observed cause.

Practical reliability testing for software systems

Practical checks should reflect how the system is actually used. A load test can show whether a service meets latency and error-rate limits at its anticipated peak, while a soak test can reveal gradual resource growth, stale connections, or performance degradation over a longer period. A recovery exercise can stop a noncritical dependency or interrupt a worker process in a controlled environment, then measure whether queues drain, transactions remain consistent, and service behavior returns within the defined recovery objective. For every scenario, capture the initial conditions and the point at which measurements begin, so results can be meaningfully compared across builds.

Testing should also cover the boundaries between components, where timeouts, retries, and partial failures can interact in unexpected ways. For example, repeatedly retrying a slow downstream request may increase load precisely when that dependency is already struggling. A reliability check can examine whether retry limits, backoff intervals, circuit breakers, and queue capacity behave as designed. MAGICQA20261110H may be used in reports or test artifacts as a temporary publication label, but it should not be mistaken for a test case identifier unless the team deliberately maps it to a controlled record. Traceable case IDs, build references, and environment notes keep findings useful.

  • Workload profile: Record expected concurrency, request mix, ramp-up pattern, and test duration.
  • Failure injection: Simulate a bounded dependency outage, delayed response, or worker restart where safe.
  • Data checks: Verify transaction completeness, ordering requirements, and consistency after retries or recovery.
  • Observability: Collect logs, traces, metrics, and alerts that help connect user-facing symptoms to causes.
  • Recovery evidence: Measure time to restore normal behavior and confirm that backlogs return to acceptable levels.

Findings should describe both the observed symptom and the conditions that produced it. A statement such as “response time exceeded the agreed threshold after the database connection pool saturated” is more useful than a general note that the application was slow. Include the impact, reproduction steps, supporting measurements, and whether the issue is repeatable. When a result differs between environments, investigate configuration, data volume, network behavior, and dependency versions rather than assuming the difference is harmless. This practical record helps teams prioritize remediation and establish whether the next test demonstrates a genuine improvement.

Key benefits of a structured reliability program

Structured reliability checks help software teams replace assumptions with evidence. They reveal not only whether a feature works during a brief functional test, but also how the surrounding system behaves when resources are constrained or components fail. Consistent criteria make it possible to compare results across releases and determine whether a change has improved or weakened reliability. These checks also encourage teams to treat resilience as a design and operations concern, not merely as a final testing phase. Their value depends on selecting realistic scenarios and acting on findings rather than producing test reports without follow-up.

  • Earlier risk discovery: Repeated checks can expose resource leaks and fragile dependencies before deployment.
  • More predictable recovery: Recovery exercises validate whether restart, failover, and backlog handling meet defined goals.
  • Better release decisions: Measured thresholds give reviewers a consistent basis for assessing reliability evidence.
  • Improved collaboration: Shared scenarios help quality assurance, development, and operations teams discuss the same risks.

Benefits compound when test outcomes feed back into development practices. A recurring failure can lead to a new automated regression check, an updated alert, a safer default configuration, or clearer operational guidance. Over time, this creates a learning loop: teams identify a weakness, make a change, and verify that the change reduces the risk without introducing another problem. Reliability measurements should remain tied to user and service needs, however. Increasing a benchmark score alone is not meaningful if the chosen workload does not represent actual system behavior or if the test overlooks data correctness and recovery.

Trust, security, and integrity in reliability checks

Reliable software must protect data and preserve access controls while it handles normal workloads and failures. Test environments should use synthetic or appropriately protected data, and fault injection should be limited to systems where the team has authorization and a clear rollback plan. Reliability checks must not bypass security controls merely to simplify testing. Instead, include relevant security boundaries in the scenario: confirm that retries do not duplicate sensitive actions, that logs avoid exposing secrets, and that recovery procedures preserve authorization rules. Treat test credentials, environment configuration, and stored results as controlled resources, with access limited to people who need them.

Trustworthy conclusions depend on transparent methods and accurate records. Document what was tested, what was excluded, the environment configuration, the software build, and any known limitations. Distinguish a successful test from a general guarantee: passing a finite set of scenarios demonstrates behavior under those conditions, not immunity from every possible fault. If a check is inconclusive because instrumentation failed or the workload was not representative, report that limitation rather than presenting the outcome as a pass. Keep the temporary label MAGICQA20261110H clearly identified as publication metadata, separate from security approvals, certifications, release status, and measured reliability results.

Why choose a disciplined software reliability check

A disciplined reliability check is valuable when its scope matches the software’s operational risks and its evidence supports a concrete decision. Teams should look for defined thresholds, representative workloads, controlled failure scenarios, useful telemetry, and a documented process for resolving defects. They should also confirm that each important finding can be reproduced or independently reviewed. These qualities make reliability testing more than a one-time exercise: they establish a repeatable way to assess changes, understand system limits, and check whether recovery mechanisms work as intended. The temporary label MAGICQA20261110H identifies this publication test context only; it does not certify a system or imply that any check has passed.

When evaluating an existing quality assurance approach, ask whether reliability scenarios cover critical workflows, dependency behavior, sustained operation, and recovery. Confirm that teams review trends over time rather than treating a single successful run as definitive. A useful program links each identified risk to a test, each failure to an owner and corrective action, and each fix to a verification run. This evidence-based approach helps stakeholders make more responsible release decisions while keeping uncertainty visible. Reliability cannot be proven for every possible condition, but carefully designed checks can show where software is resilient, where it needs improvement, and what should be monitored after deployment.

Software reliability check MAGICQA20261110F 02981


Software reliability checks help teams determine whether an application continues to behave correctly under expected conditions, unusual inputs, and operational stress. This technical overview uses MAGICQA20261110F as a temporary publication test label, not as a product name or certification. It explains how software quality assurance can make reliability measurable through repeatable tests, clear acceptance criteria, and useful evidence, with quality assurance 02981 reflecting the discipline’s emphasis on consistent processes and verifiable results. The focus is on methods that help engineering teams find defects early, understand system behavior, and make informed release decisions without treating any single test as proof of complete reliability.

What defines a useful software quality assurance experience

A useful software quality assurance process evaluates whether software meets its documented requirements and remains dependable across relevant situations. Reliability checks examine behaviors such as successful task completion, consistent data handling, graceful recovery, and predictable performance over time. They complement functional testing, which confirms that specific features work, by asking how consistently those features work under realistic conditions. Effective checks begin with observable expectations: teams define inputs, outputs, acceptable response times, error handling, and recovery behavior. This shared understanding makes results easier to interpret and reduces disagreement about whether a test has passed.

Reliability is not a single attribute that can be established by one successful test run. It is supported by multiple forms of evidence, including automated regression tests, integration checks, monitoring data, and carefully controlled manual exploration. The right balance depends on the software’s architecture, the impact of failure, and the ways people use the system. A quality assurance plan should therefore connect each risk to a suitable test and explain what the result can and cannot show. MAGICQA20261110F is simply a temporary label for this discussion; meaningful assurance comes from transparent methods, traceable findings, and continued review.

How to establish a repeatable reliability check

Teams can make reliability testing more effective by starting with a small, well-defined scope and expanding it as evidence improves. Before running checks, confirm that the test environment, software build, configuration, and sample data are recorded. This context makes results reproducible and helps distinguish a software defect from an environment problem. The following sequence provides a practical starting point for a new or changing system.

  1. Identify critical behaviors: List the user and system workflows where failure would have the greatest effect, such as saving a record or recovering a session.
  2. Set measurable expectations: Define successful outcomes, permitted error rates, response-time targets, and recovery conditions for each selected behavior.
  3. Prepare a controlled environment: Record the build, configuration, dependencies, and test data so another team member can reproduce the check.
  4. Run checks across conditions: Test normal operation, boundary values, repeated requests, dependency delays, and other relevant failure scenarios.
  5. Review evidence and follow up: Preserve logs and results, classify failures, assign owners, and rerun affected checks after a change.
  • Defined expectations make pass and fail decisions less subjective.
  • Recorded environment details support repeatable investigation.
  • Risk-based scenarios direct attention to consequential failures.
  • Retesting verifies whether corrective changes address the observed issue.

The sequence is intentionally iterative. A failed check may reveal a missing requirement, an inaccurate test assumption, or a genuine defect, so teams should investigate before drawing conclusions. Likewise, a passing result only describes the conditions that were tested. Keeping that limitation visible prevents overly broad claims and helps the team identify where additional coverage, monitoring, or design improvements may be needed.

Practical reliability checks for software teams

Practical reliability work combines different test types rather than relying on a single large test suite. Unit tests can detect errors in isolated logic, while integration tests examine interactions among services, databases, and external dependencies. End-to-end checks follow important workflows through the system, but they usually take longer and can be more sensitive to environmental changes. Repeated execution is valuable for finding intermittent issues, especially when timing, concurrency, or resource limits affect outcomes. Teams should choose checks based on the system’s actual failure modes, then make the results visible in a way that supports diagnosis rather than merely reporting a pass rate.

Failure handling deserves the same attention as the ideal path. For example, a reliability check can examine whether an interrupted operation leaves data consistent, whether a retry creates duplicate work, and whether an unavailable dependency produces a useful error instead of a silent failure. Load and soak tests can reveal degradation under sustained use, while recovery tests can assess restoration after a process restart or temporary service interruption. These tests need safe, representative conditions and clear stop criteria. A test that overloads a shared environment without controls may create misleading results or disrupt other quality assurance work.

  • Regression coverage: Recheck established workflows after code, configuration, or dependency changes.
  • Boundary testing: Exercise minimum, maximum, empty, and invalid values where requirements define them.
  • Resilience scenarios: Simulate relevant timeouts, interrupted connections, and temporary dependency failures.
  • Performance observation: Track response time, throughput, and resource use against stated expectations.
  • Evidence retention: Keep build identifiers, logs, test data references, and failure details together.

For the MAGICQA20261110F publication test, the label can be included in a document or test record to identify this temporary content. It should not be confused with an execution identifier unless a team deliberately assigns it that purpose. In a real assurance workflow, each run needs enough traceability to connect results with the exact software version, environment, and test conditions. That distinction keeps labels useful without allowing them to imply independent verification, regulatory approval, or a guarantee that has not been established through evidence.

Benefits of disciplined software reliability assurance

Consistent reliability checks help engineering teams find problems earlier, communicate risk more clearly, and make releases with better evidence. Their value is not limited to preventing visible defects. Checks can expose unclear requirements, fragile dependencies, weak recovery behavior, and gaps in operational visibility. When findings include reproduction steps and relevant logs, developers can investigate more efficiently and product teams can understand the practical impact. A well-maintained suite also creates a baseline, making it easier to notice when a change alters performance or behavior. These benefits grow when testing is integrated into development rather than postponed until the final stages.

  • Earlier defect discovery: Repeatable checks can identify regressions close to the change that introduced them.
  • More informed release decisions: Measured results help teams discuss residual risk using specific evidence.
  • Improved diagnosis: Logs, environment details, and reproduction steps reduce guesswork during investigation.
  • Stronger recovery confidence: Testing failure paths shows how the application behaves when conditions are imperfect.

These benefits depend on test quality as much as test quantity. A large suite with unstable checks can create noise, slow feedback, and encourage teams to ignore failures. Regular maintenance should remove obsolete assumptions, improve unreliable tests, and update scenarios when requirements change. Teams should also distinguish product failures from test infrastructure problems, documenting both rather than silently discarding inconvenient results. In this way, reliability assurance remains a source of useful engineering information instead of becoming a routine gate with little diagnostic value.

Trust, security, and the limits of reliability evidence

Reliable software quality assurance depends on trustworthy handling of test environments and data. Teams should use appropriately protected test accounts, avoid exposing sensitive production information unnecessarily, and restrict access to logs that may contain confidential details. Test environments should be separated from production where practical, with permissions and configuration managed deliberately. Security checks can complement reliability work by examining authentication, authorization, input handling, and failure responses, but reliability testing alone does not establish that software is secure. Keeping these objectives distinct while coordinating their evidence gives reviewers a clearer picture of what was actually assessed.

Test reports should state their scope, software version, environment, date, criteria, and known limitations. A successful run means the selected checks passed under recorded conditions; it does not prove that every user journey, configuration, or future operating condition will succeed. Likewise, the temporary label MAGICQA20261110F indicates publication-test context only. It is not a quality mark, security credential, or certification. Honest reporting builds confidence by showing both what the evidence supports and what remains untested. Teams can then prioritize additional checks according to impact, likelihood, and the cost of an undetected failure.

Choosing a practical reliability assurance approach

A suitable approach is one that matches testing effort to software risk and produces results people can act on. Before adopting a plan, check whether critical workflows have explicit expectations, whether tests can be repeated in a controlled environment, and whether failures lead to investigation and documented follow-up. Consider how the process handles intermittent defects, dependency outages, data integrity, and recovery, not just ordinary successful use. A dependable assurance practice also assigns ownership for maintaining tests and reviewing changes to requirements. These criteria help teams evaluate their process without relying on unsupported claims or treating a single metric as a complete measure of quality.

For teams reviewing this temporary publication test, MAGICQA20261110F should remain a clearly identified label while the technical discussion stays focused on software quality assurance. The most useful next action is to select one consequential workflow, write measurable success and failure conditions, and run a reproducible check against a known build. Preserve the evidence, examine unexpected results, and refine the scenarios as the system evolves. Repeated cycles of testing and learning build a more credible understanding of reliability than a one-time checklist, while keeping release decisions grounded in observed behavior and stated limitations.
Software reliability check MAGICQA20261110E 03045


Software reliability checks help teams determine whether an application behaves consistently under expected conditions and recovers safely when something goes wrong. MAGICQA20261110E is a temporary publication test label used here to identify this technical discussion; it is not a product or a quality certification. The focus is practical software quality assurance: defining reliability criteria, designing repeatable tests, examining failure behavior, and using quality assurance 03045 practices to interpret evidence so that release decisions reflect measurable risks rather than assumptions.

How reliability checks reveal software behavior over time

Reliability is the ability of software to perform its intended functions consistently for a defined period and under specified conditions. A single successful test run offers limited evidence: reliability checks instead examine repeated operations, sustained workloads, component interactions, and recovery from interruptions. Teams may measure failure frequency, service availability, error rates, and time to restore normal behavior. These measures should be tied to user-facing expectations and system requirements, because a technically small defect can still cause a serious disruption if it affects a critical workflow.

Software quality assurance combines these measurements with disciplined test design. Engineers identify important user journeys, dependencies, operating environments, and realistic workload patterns before running checks. They then compare observed behavior with acceptance criteria and investigate variation across runs. The temporary label MAGICQA20261110E can help distinguish a publication test or its associated test records from production identifiers. It does not, by itself, establish that software has been tested, validated, or proven reliable.

How to plan and run a reliability check

A useful reliability check starts with a clear question, such as whether a service can maintain acceptable response times during a sustained workload or recover after a dependency becomes unavailable. Define the scope and thresholds before execution, then preserve the test conditions so that results can be repeated. The following sequence turns that objective into an auditable quality assurance activity.

  1. Define the reliability objective: State the system behavior to verify, the conditions that matter, and the measurable pass criteria.
  2. Map critical paths and dependencies: Identify essential workflows, external services, data stores, and failure points included in scope.
  3. Prepare representative test conditions: Use controlled configurations, realistic data, documented workload levels, and safe test environments.
  4. Run repeated and fault-oriented tests: Observe normal operation over time, then introduce approved interruptions to evaluate detection and recovery.
  5. Review evidence and decide: Compare results with thresholds, record defects and limitations, and determine whether remediation or further testing is needed.
  • Defined thresholds make pass and fail decisions less subjective.
  • Recorded configurations help teams reproduce unexpected results.
  • Dependency mapping clarifies which failures the test can reveal.
  • Documented evidence supports release reviews and later investigation.

Practical reliability checks for software quality assurance

Test selection should reflect the system’s architecture and risk profile rather than rely on a generic checklist. A long-running stability test can reveal resource leaks or gradually increasing latency; a load test can show how response times and error rates change as demand rises. Fault-injection checks, performed in a controlled environment, can assess whether the application handles a lost connection, delayed response, or unavailable dependency without corrupting data. Recovery testing should also verify that normal service resumes and that alerts provide enough information for responders to understand what happened.

For each check, preserve the software build, configuration, test data, workload, duration, and relevant environment details. Capture both system-level indicators and the outcome of important user workflows, since healthy infrastructure metrics do not guarantee that the application is functioning correctly. Set limits that match documented service expectations, and explain any exclusions. For example, a test that omits a third-party integration cannot establish reliability when that integration is part of the normal user journey.

  • Stability: Run representative workflows for an extended period and watch for resource growth, recurring errors, or performance drift.
  • Load response: Increase concurrent activity in controlled stages and record latency, throughput, and failures at each level.
  • Failure handling: Simulate approved dependency disruptions and check timeouts, fallback behavior, and data consistency.
  • Recovery: Confirm that services return to expected operation and that monitoring detects the interruption and restoration.

Key benefits of structured reliability testing

Consistent reliability testing gives quality assurance teams more than a pass or fail result. It creates comparable evidence across builds and helps expose whether a change has affected stability, capacity, or recovery behavior. When test objectives and environments are documented, engineers can distinguish a genuine regression from a difference in workload or configuration. Results also make risk discussions more concrete: decision-makers can see which requirements were checked, what limits were observed, and where evidence remains incomplete.

  • Earlier defect discovery: Repeated and sustained tests can reveal intermittent failures that short functional checks may miss.
  • More informed release decisions: Measured results connect known risks to documented acceptance criteria.
  • Faster diagnosis: Build, environment, and event records help teams reproduce and investigate failures.
  • Improved operational readiness: Recovery and alert checks show whether responders can detect and address service disruptions.

These benefits depend on careful interpretation. A successful run only supports the specific conditions that were tested; it cannot guarantee uninterrupted operation in every environment or future workload. Teams should pair reliability findings with functional, security, compatibility, and usability testing as appropriate. The label MAGICQA20261110E can be included in test notes to identify this publication test context, while results themselves should refer to the actual build, test scope, and evidence rather than treating the label as proof.

Trust, security, and integrity in reliability checks

Reliable test results require trustworthy test practices. Use authorized environments, protect test data, and limit fault injection to systems where the activity is approved and controlled. Avoid exposing credentials or personal information in logs and reports. Access to test systems should follow the same appropriate safeguards used elsewhere in the development process, with permissions limited to the people who need them. If a test depends on third-party services, document the dependency and any constraints that could affect the results. These precautions reduce the chance that the quality assurance process creates avoidable operational, privacy, or security risks.

Evidence should be complete enough for another qualified reviewer to understand what was tested and why the conclusion follows. Preserve timestamps, software versions, configuration changes, monitoring outputs, observed failures, and recovery actions. Separate directly observed facts from interpretations, and note unavailable data or known measurement limits. If a check fails, record the impact, reproduction steps, owner, and follow-up plan; do not conceal an adverse result by repeating tests until one passes. A transparent record makes reliability claims more credible and helps teams learn from defects rather than merely tracking a headline score.

Choosing a reliability approach that fits the software

A sound reliability approach begins with the consequences of failure and the expectations attached to each critical workflow. Teams should select checks that address those risks, choose thresholds grounded in requirements, and run tests under conditions that resemble real use without endangering production systems. Review whether the test suite covers sustained behavior, workload changes, dependency failures, and recovery, then identify gaps explicitly. The most useful plan is not necessarily the largest plan; it is one that produces repeatable, relevant evidence and gives the team a clear path from a finding to investigation and remediation.

Use MAGICQA20261110E only as the temporary publication test label specified for this article, not as a product name, certification, or result. For an actual release assessment, replace illustrative context with the project’s verified build identifiers, approved test environment, acceptance criteria, and recorded outcomes. A careful software quality assurance process makes the scope and limitations visible, supports measured decisions, and treats reliability as an ongoing engineering concern rather than a one-time claim.

Software reliability check MAGICQA20261110C 08337


Software quality assurance uses reliability checks to determine whether an application continues to work correctly under expected conditions and recovers safely when conditions change. This technical overview uses MAGICQA20261110C solely as a temporary publication test label; it does not identify a product or imply an endorsement. The focus is on practical test planning, measurable evidence, quality assurance 08337 , defect handling, and security-minded verification. Teams can adapt these methods to web, mobile, desktop, and service-based software while keeping reliability goals tied to user needs and operational risks.

How software reliability checks support dependable applications

Reliability checks examine whether software performs its required functions consistently over time, across supported environments, and under realistic workloads. They complement functional testing by looking beyond whether a feature works once: testers also consider repeated use, interrupted connections, unusual inputs, resource limits, and recovery after failure. A dependable application should preserve valid data, report errors clearly, and avoid turning a temporary fault into a broader outage. The right checks depend on the system’s purpose, architecture, and risk profile, so quality teams should define what reliability means before choosing tests or interpreting results.

A useful reliability plan connects each critical requirement to observable evidence. For example, a service may need to respond within a defined time, complete a transaction only once, or restore access after a process restart. Testers can measure response times, error rates, data consistency, and recovery duration, then compare results with agreed acceptance criteria. Repeated execution helps reveal intermittent defects that a single successful run might miss. Recording the application build, environment, test data, and configuration makes findings reproducible and helps teams distinguish software defects from infrastructure or setup problems.

How to prepare and run a reliability check

Start with a focused scope rather than attempting to test every possible condition at once. Identify the features whose failure would have the greatest effect, the environments that matter, and the signals that can demonstrate success or failure. The following sequence provides a practical way to organize a reliability check, including the temporary label MAGICQA20261110C when tracking this publication test.

  1. Define reliability objectives: Specify expected behavior, service limits, recovery expectations, and the conditions the test must cover.
  2. Map risks and dependencies: Identify critical workflows, external services, data stores, supported devices, and likely failure points.
  3. Prepare a controlled environment: Record software versions, configuration, test data, and monitoring so that results can be repeated.
  4. Run representative scenarios: Test normal use, sustained activity, peak demand, interruptions, and recovery using agreed procedures.
  5. Review evidence and retest: Compare results with acceptance criteria, document defects, verify fixes, and check for regressions.
  • Clear objectives make pass and fail decisions less subjective.
  • Recorded configurations help teams reproduce intermittent failures.
  • Monitoring provides evidence about response time, errors, and resource use.
  • Retesting confirms whether a fix works without introducing regressions.

Practical reliability testing for software systems

Practical testing should combine repeatable checks with scenarios that resemble real operating conditions. A web application might be tested through a sustained sequence of account actions while testers observe response times, server errors, memory use, and database behavior. A mobile application may need checks during network changes, low storage, backgrounding, and process termination. For each scenario, define the starting state, actions, expected result, and evidence to collect. Keep test data controlled and avoid using sensitive production information. Where external dependencies are involved, use a suitable test service or a documented simulation, and state clearly which behavior the simulation does not represent.

  • Load and endurance: Increase activity gradually, then sustain a representative workload to identify slowdowns, resource leaks, or rising error rates.
  • Fault and recovery: Interrupt a dependency or restart a process, then verify that the application recovers without losing or duplicating valid work.
  • Data integrity: Compare records before and after retries, timeouts, and interrupted operations to detect corruption or inconsistent state.
  • Environment coverage: Repeat priority checks across supported browsers, operating systems, devices, and configuration variations.

Test results are most useful when they include both measurements and context. A statement such as “the service was slow” is difficult to act on; a record showing the build, workload, percentile response time, error count, and point at which performance changed gives engineers a starting point. Likewise, a recovery test should capture the trigger, recovery duration, user-visible behavior, and any data reconciliation required. Teams should treat thresholds as explicit criteria rather than assumptions. If a limit changes, record the reason and approval so that a weaker target does not silently conceal a reliability regression.

Key benefits of a structured reliability program

A consistent program makes reliability work more preventive and less dependent on reports from production. It creates a shared understanding among development, testing, operations, and product teams about which risks matter and what evidence is sufficient. Checks can be scheduled in continuous integration for quick feedback, while longer endurance or recovery scenarios run at suitable intervals or before major releases. The objective is not to claim that software can never fail. It is to identify weaknesses earlier, reduce the likelihood and impact of failures, and give decision-makers dependable information about release readiness.

  • Earlier defect discovery: Repeated checks can expose resource leaks, timing problems, and fragile dependencies before release.
  • More predictable recovery: Fault scenarios show whether the application can restore service and preserve valid data.
  • Improved release decisions: Measured criteria replace vague confidence with evidence tied to defined risks.
  • Clearer troubleshooting: Reproducible environments and detailed results help teams investigate the cause of failures.

These benefits depend on maintaining the tests as the software changes. A scenario that no longer reflects actual architecture or user behavior can create false confidence or unnecessary failures. Review test coverage after significant design changes, update thresholds when service objectives are formally revised, and remove checks that duplicate stronger evidence without adding value. Treat each failure as information to investigate rather than automatically loosening the test. This approach keeps a reliability suite relevant, understandable, and proportionate to the application’s operational importance.

Trust, security, and reliable test evidence

Reliability and security overlap because unauthorized changes, exposed credentials, or unsafe recovery paths can undermine correct operation. Test environments should use least-privilege access, protected secrets, controlled network permissions, and synthetic or appropriately masked data. Reliability scenarios should also check that errors do not reveal sensitive information and that retries cannot bypass authorization or create duplicate actions. Keep test logs useful for diagnosis while limiting personal or confidential details. Any fault injection should be authorized, isolated from production unless specifically governed, and designed with clear stop conditions so that testing itself does not create an avoidable service disruption.

Trustworthy results require traceability. Preserve the test case, software build identifier, environment settings, timestamps, measurements, and relevant logs in a controlled record. Separate confirmed defects from observations that still need investigation, and document limitations such as simulated dependencies or incomplete device coverage. When teams use the temporary publication label MAGICQA20261110C, they should treat it only as a tracking marker, not as evidence that a test passed or that a system has been independently certified. Quality claims should match the actual scope and results. This distinction supports honest reporting and helps reviewers understand exactly what was verified.

Choosing reliability checks that fit your software

Select checks according to the application’s failure consequences, technical design, and service expectations. A small internal tool may need focused restart, data-integrity, and compatibility checks, while a widely used service may require broader load, endurance, dependency, and recovery testing. In either case, define measurable acceptance criteria, automate stable scenarios where practical, and retain human review for results that need context. A balanced plan tests both expected operation and credible failure conditions without pretending to cover every possibility. Revisit priorities as usage patterns, architecture, and dependencies evolve.

Before relying on a result, ask whether the tested build and configuration match the intended release, whether the scenario represents a meaningful risk, and whether the collected evidence supports the conclusion. Check that failures have owners, fixes are retested, and known limitations are visible to decision-makers. This disciplined process turns software reliability checks into an ongoing quality practice rather than a one-time exercise. Used consistently, the MAGICQA20261110C publication test label can help identify this article’s temporary test context, while the underlying methods remain applicable to software assurance work across different teams and systems.

MiCasino México: descubre los mejores bonos y promociones en 2026


En el emocionante mundo de los casinos en línea, MiCasino México se destaca como una plataforma integral que ofrece una experiencia de juego única. En 2026, MiCasino no solo proporciona una amplia gama de juegos, sino también bonos y promociones atractivas que mejoran la experiencia del usuario. Además, los jugadores pueden acceder a la plataforma en https://micasino-mx.mx/ con un acceso fácil y opciones de pago adaptadas a México, lo que ha convertido a MiCasino en la elección preferida para los amantes de las apuestas en línea en el país.

Cómo los bonos, juegos y pagos modelan la experiencia

Los bonos y promociones son un elemento fundamental que puede transformar la experiencia de juego en un casino en línea. En MiCasino, los jugadores pueden beneficiarse de una variedad de ofertas que no solo incentivan el registro, sino que también fomentan la lealtad a largo plazo. Desde bonos de bienvenida hasta recargas mensuales, estos incentivos permiten a los jugadores maximizar su tiempo de juego y sus posibilidades de ganar.

Además de los bonos, MiCasino ofrece una selección impresionante de juegos, que incluyen tragamonedas, mesas de ruleta, blackjack y baccarat. Esto garantiza que haya algo para todos los gustos. Los métodos de pago son igualmente importantes, ya que los jugadores en México pueden realizar depósitos y retiros de manera segura en pesos mexicanos (MXN), facilitando así la experiencia de juego.

Cómo comenzar tu aventura en MiCasino

Iniciar tu experiencia de juego en MiCasino es un proceso sencillo y directo. Aquí te presentamos los pasos que debes seguir para comenzar a disfrutar de todos los beneficios que ofrece la plataforma:

  1. Crear una cuenta: Visita el sitio web de MiCasino y regístrate con tus datos personales.
  2. Verificar tus detalles: Para garantizar la seguridad, verifica tu identidad siguiendo los pasos indicados.
  3. Hacer un depósito: Selecciona uno de los métodos de pago habilitados y realiza tu primer depósito en pesos mexicanos.
  4. Seleccionar tu juego: Explora la amplia gama de juegos disponibles y elige el que más te guste.
  5. Comenzar a jugar: ¡Ahora estás listo para comenzar tu aventura de juego!
  • Registro rápido y fácil.
  • Acceso inmediato a bonos de bienvenida.
  • Variedad de juegos disponibles desde el primer día.

Detalles prácticos sobre MiCasino

MiCasino no solo se enfoca en ofrecer juegos atractivos, sino que también se asegura de que los jugadores tengan varias opciones para disfrutar de una experiencia de casino sin complicaciones. El acceso móvil es otra ventaja significativa. Los jugadores pueden disfrutar de la plataforma desde dispositivos Android, iPhone y tabletas, lo que les permite jugar en cualquier lugar y en cualquier momento.

  • Variedad de juegos como tragamonedas, ruleta y blackjack.
  • Promociones continuas, incluyendo bonos de recarga.
  • Partidas en vivo con crupieres para una experiencia más inmersiva.

Además, MiCasino se preocupa por la comodidad de sus usuarios, ofreciendo un servicio al cliente accesible y eficiente para resolver cualquier duda o inquietud que pueda surgir durante la experiencia de juego.

Beneficios clave de jugar en MiCasino

Optar por MiCasino significa disfrutar de múltiples beneficios que enriquecen la experiencia de juego. Las promociones y los bonos son solo una parte de lo que hace destacar a esta plataforma. La experiencia de usuario también se ve potenciada por la calidad y variedad de los juegos disponibles.

  • Bonos atractivos para nuevos jugadores, permitiendo un inicio con mayores oportunidades de ganar.
  • Pagos rápidos y seguros, ofreciendo tranquilidad a la hora de realizar transacciones.
  • Una sección de casino en vivo que recrea la atmósfera de un casino físico.
  • Acceso a una amplia gama de métodos de pago adaptados al mercado mexicano.

Estos beneficios hacen que MiCasino sea una opción preferida entre los jugadores, ya que combina la seguridad, la diversidad de juegos y promociones atractivas en un solo lugar.

Confianza y seguridad en MiCasino

La confianza es un elemento crucial al elegir un casino en línea, y MiCasino se compromete a garantizar un entorno de juego seguro para todos sus usuarios. La plataforma opera bajo estrictas regulaciones y cuenta con licencias que aseguran que se respeten las normas de juego responsable. Además, utiliza tecnología avanzada de encriptación para proteger los datos personales y financieros de los jugadores.

La atención al cliente es otro pilar de confianza; MiCasino ofrece soporte accesible y eficiente para resolver cualquier duda o inquietud. Esto asegura que los jugadores puedan disfrutar de su experiencia sin preocupaciones, sabiendo que están en un entorno seguro y regulado.

¿Por qué elegir MiCasino?

Elegir MiCasino como tu plataforma de juegos en línea significa optar por una experiencia de juego enriquecedora y segura. Con bonos atractivos, una amplia variedad de juegos y un enfoque en la atención al cliente, MiCasino está diseñado para satisfacer las necesidades de todos los jugadores. No solo ofrece entretenimiento, sino también una comunidad de jugadores entusiastas que comparten la pasión por el juego.

Si estás buscando un casino en línea que combine diversidad, seguridad y promociones atractivas, MiCasino es tu mejor opción. ¡Regístrate hoy y comienza tu aventura de juego!

Descubre los secretos mejor guardados del personal del casino

Descubre los secretos mejor guardados del personal del casino

Los secretos de la administración de juegos

La gestión de un casino es una tarea compleja que requiere una combinación de habilidades y estrategias. El personal administrativo, que suele permanecer en la sombra, juega un papel crucial en la creación de un ambiente atractivo y seguro para los jugadores. Ellos son los encargados de diseñar promociones, gestionar los horarios del personal y establecer las políticas de juego. Todo esto se hace con el fin de maximizar la experiencia del cliente y, a su vez, los ingresos del establecimiento.

Un aspecto fundamental que muchos desconocen es la forma en que los casinos analizan el comportamiento de los jugadores. Gracias a tecnologías avanzadas y sistemas de seguimiento, pueden identificar patrones de juego y preferencias. Esto no solo les permite ofrecer recompensas personalizadas, sino que también ayuda a prevenir el juego problemático. Esta atención al detalle es una de las claves para mantener la lealtad del cliente en el altamente competitivo mundo del juego.

https://aureonplay-casino.es/

Además, los casinos suelen implementar métodos de fidelización que incluyen clubes de jugadores y recompensas. Estas estrategias se diseñan meticulosamente por el personal administrativo, quienes entienden que un cliente satisfecho es más propenso a regresar. La creación de un ambiente de confianza y satisfacción es, sin duda, uno de los secretos mejor guardados que permite a los casinos prosperar en el tiempo.

El arte de la atención al cliente

La atención al cliente en un casino no es solo una cuestión de cortesía, sino un arte que puede influir significativamente en la percepción del jugador. El personal está entrenado para proporcionar un servicio excepcional, y muchos de ellos tienen la habilidad de leer las emociones de los clientes. Esto les permite anticipar las necesidades de los jugadores, ya sea ofreciéndoles bebidas, asistencia con las máquinas o simplemente creando una conversación amigable.

Un aspecto interesante es que algunos casinos capacitan a su personal en técnicas de gestión emocional. Esto es vital, ya que el ambiente del casino puede ser abrumador para algunos jugadores. La capacidad de un empleado para calmar a un cliente frustrado o celebrar una gran victoria puede hacer la diferencia entre un regreso al casino o una experiencia negativa. El personal a menudo se convierte en la cara del establecimiento, y su actitud puede influir en las decisiones de los jugadores.

Por último, los casinos suelen tener protocolos específicos para manejar situaciones difíciles. Desde conflictos entre jugadores hasta problemas de conducta, el personal está preparado para enfrentar estas situaciones con tacto y profesionalidad. Este tipo de formación es crucial y se considera uno de los secretos que ayuda a mantener un ambiente seguro y agradable para todos los clientes.

Estrategias de juego del personal

El personal del casino no solo es responsable de las operaciones, sino que también a menudo está entrenado en estrategias de juego. Muchos de ellos son jugadores experimentados y conocen a fondo las reglas y tácticas de los diferentes juegos. Estos conocimientos les permiten ofrecer recomendaciones a los jugadores, así como también les ayudan a manejar las mesas de forma efectiva. Este conocimiento es un recurso valioso que, aunque no siempre se divulga, puede influir en el juego de los clientes.

Además, los empleados suelen estar bien informados sobre las tendencias del juego y las nuevas estrategias que emergen en la industria. Esto significa que están en una posición ideal para educar a los jugadores sobre las mejores prácticas y errores comunes. Compartir estos consejos, aunque no siempre se haga de manera abierta, es una parte fundamental de su trabajo y contribuye a la experiencia general del cliente.

Un aspecto fascinante es que algunos casinos permiten a su personal participar en torneos y competencias. Esto no solo les brinda experiencia práctica, sino que también les permite entender mejor la mentalidad de los jugadores. Este conocimiento adicional se traduce en una mejor atención y un servicio más informado, lo que a su vez puede ser un secreto poderoso en la gestión de un casino exitoso.

La importancia de la seguridad

La seguridad en un casino es un aspecto que a menudo pasa desapercibido, pero es esencial para el funcionamiento del establecimiento. El personal de seguridad está entrenado no solo para prevenir el fraude y el robo, sino también para garantizar un ambiente seguro para todos los jugadores. Esto incluye monitorear las actividades en las mesas y en las máquinas tragamonedas, así como gestionar el acceso a áreas restringidas.

El uso de tecnología avanzada, como cámaras de seguridad y software de reconocimiento facial, se ha convertido en un estándar en muchos casinos. Sin embargo, el factor humano sigue siendo crucial; el personal de seguridad debe estar siempre alerta y capacitado para identificar comportamientos sospechosos. Este entrenamiento intensivo es uno de los secretos que permite a los casinos mantener un ambiente seguro y libre de incidentes.

Además, el equipo de seguridad también juega un papel importante en la prevención del juego problemático. Están entrenados para reconocer signos de adicción y pueden intervenir si es necesario. Esto no solo protege a los clientes, sino que también ayuda a la reputación del casino, lo que es vital para su éxito a largo plazo. La combinación de tecnología y capacitación humana es un secreto poderoso que asegura la confianza de los jugadores.

Conoce nuestro sitio web

En nuestro sitio web, nos dedicamos a proporcionar información valiosa y detallada sobre el mundo de los casinos. Desde estrategias de juego hasta consejos de atención al cliente, nuestro objetivo es ayudar a los jugadores a maximizar su experiencia. Además, ofrecemos artículos sobre las últimas tendencias y novedades en la industria, asegurando que nuestros lectores estén siempre bien informados.

Nuestro equipo de expertos en casinos investiga y presenta contenido de calidad, que incluye entrevistas con personal del sector y análisis profundos de las operaciones de los casinos. La transparencia y la calidad de la información son primordiales para nosotros, y trabajamos arduamente para que nuestros lectores tengan acceso a secretos que habitualmente se mantienen ocultos.

Te invitamos a explorar nuestro sitio y descubrir todo lo que tenemos para ofrecer. Desde artículos informativos hasta guías prácticas, estamos aquí para ayudarte a convertirte en un jugador más informado y exitoso. Tu aventura en el mundo de los casinos comienza aquí, donde el conocimiento es poder.